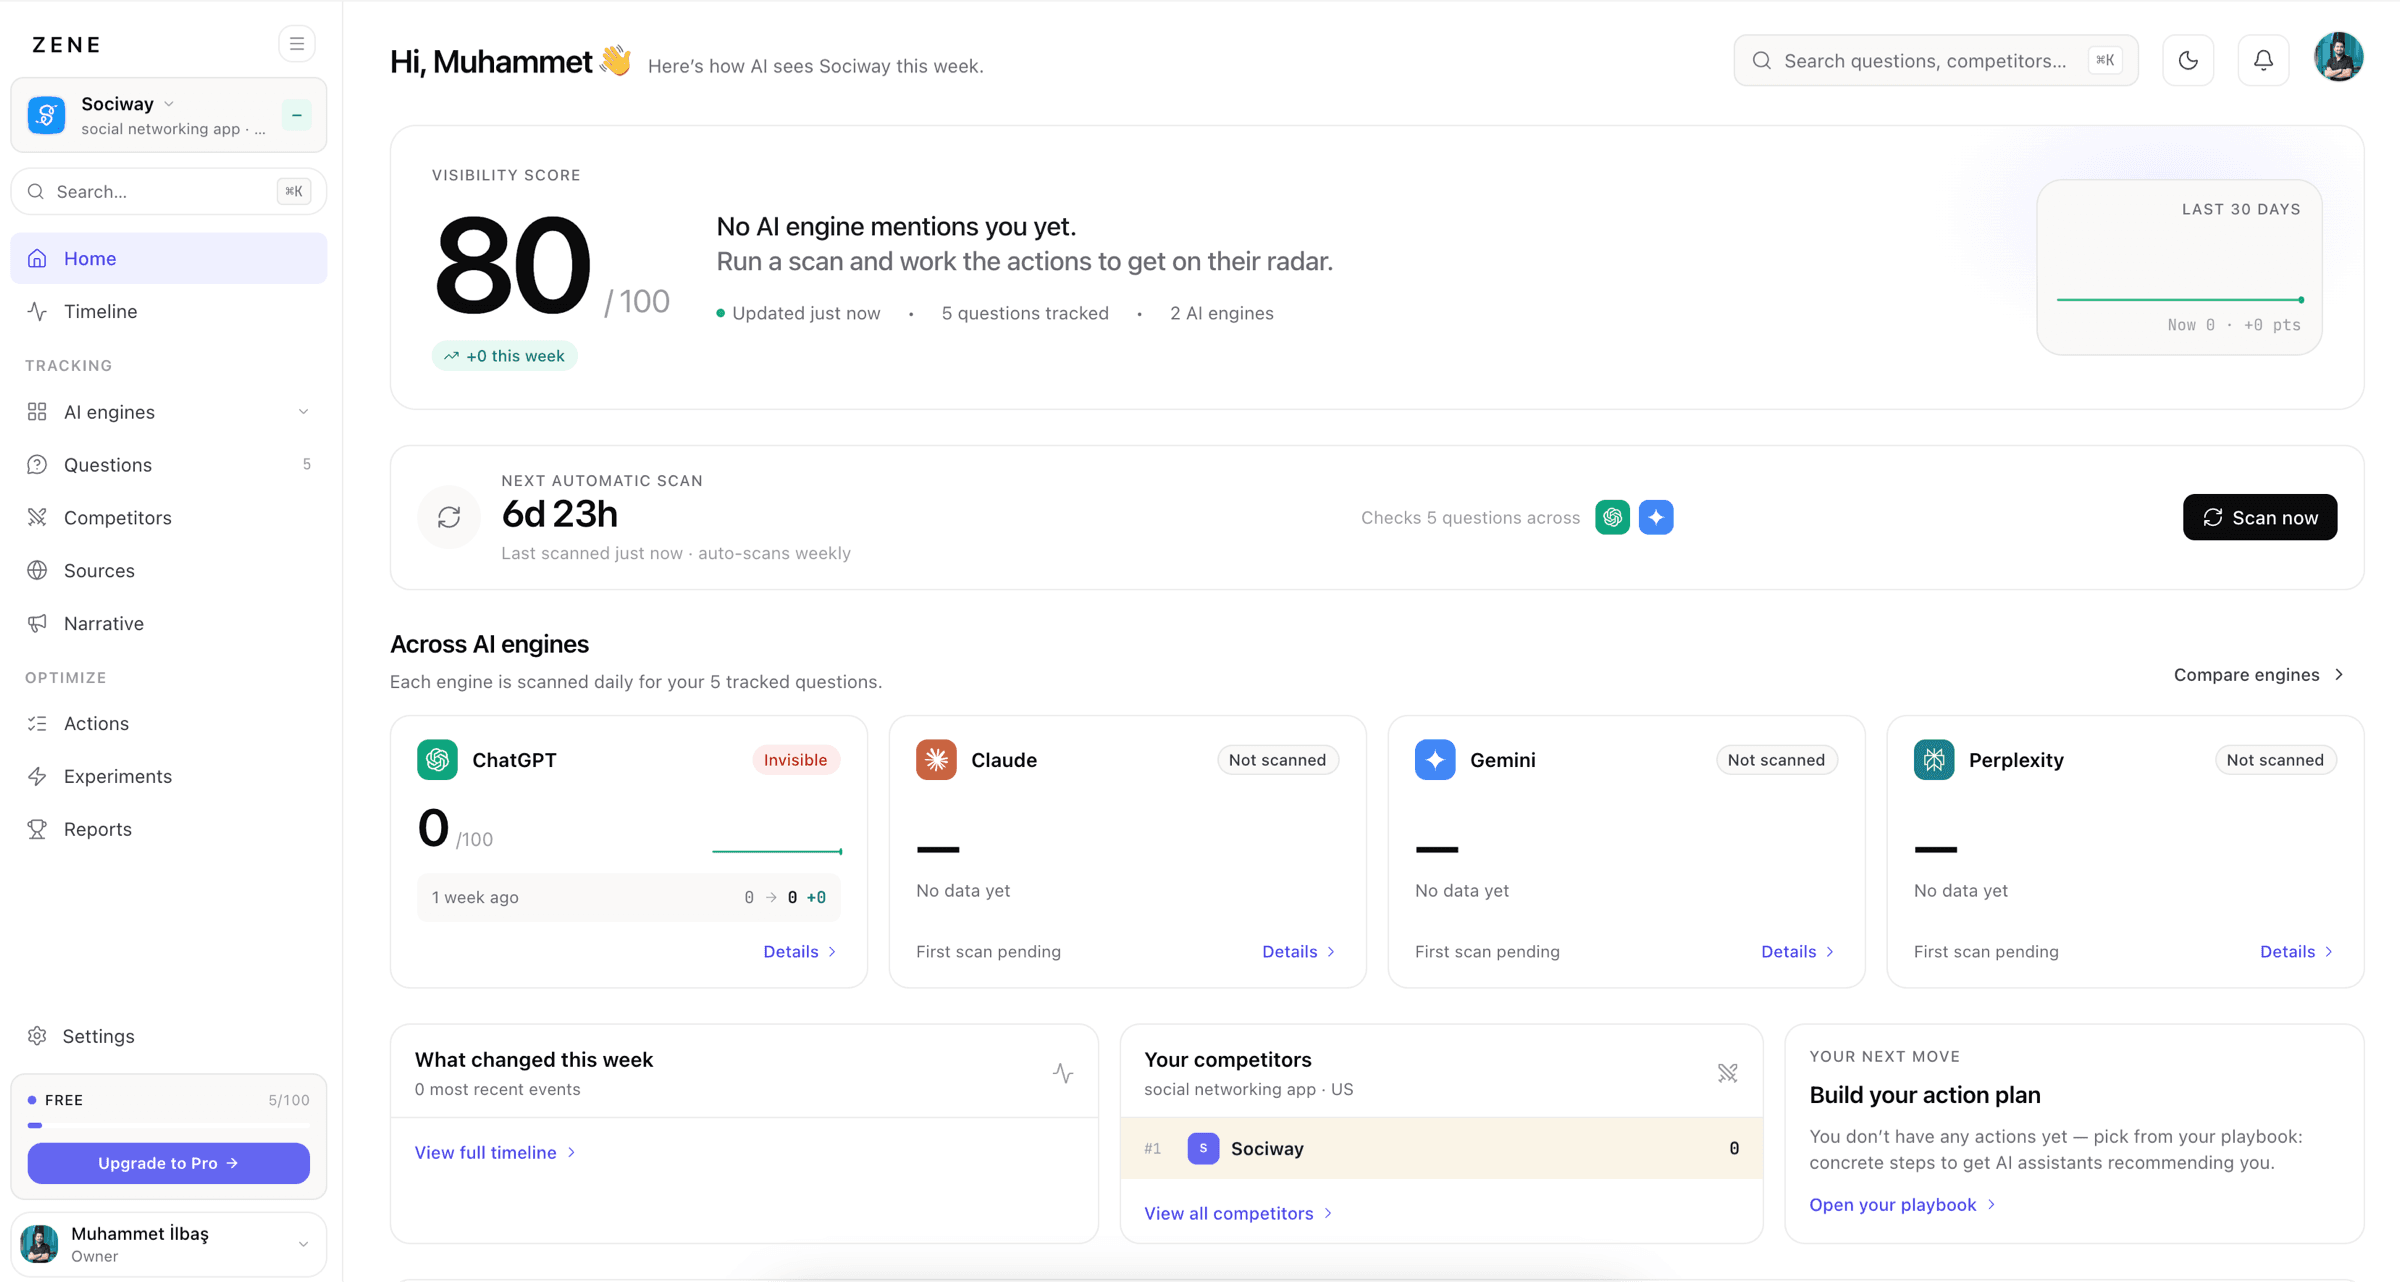
Ask the same question two ways and you can get two different ChatGPT answers. One comes from the API - the model replying from memory. The other comes from the app your buyers actually open - where ChatGPT searches the live web, reads pages, and cites the sources it used. Most tools that claim to track "your visibility in AI" only ever see the first one. Your customers only ever see the second.
That gap isn't a rounding error. It's the difference between grading a cached photocopy of reality and reading the answer that actually wins or loses you a customer. This piece is about why the two disagree, how to tell them apart, what the gap means if you care where AI sends people - and the unglamorous reason almost everyone ships the cached version anyway.
Two answers, two machines
The API and the consumer app share a brand name and not much else. They are different machines with different supply chains, and confusing them is the single most common mistake in this whole field.
The API is a request straight to the model's weights. It was trained up to a cutoff date, and by default it does not touch the live web - it answers from what it absorbed in training. It's fast, cheap and roughly repeatable, which makes it perfect for building features on top of. It makes a terrible mirror of "what ChatGPT tells my buyers," because that isn't the question it's answering.
The app at chatgpt.com does something else entirely. It classifies the intent behind your question, and for a huge share of real questions it reaches for a browse tool, runs a live web search, reads a handful of pages, and stitches the result back into the answer - with a list of citations underneath. That is not the model talking from memory. That is the model reading the open web, right now, in front of your customer.
Rule of thumb: the API answers from then (its training cutoff). The app answers from now (a live search). If you only ever query the API, you are measuring a brand's standing as of months ago - not what a buyer sees today.
Why they disagree - and it isn't noise
When the two answers diverge, it's for structural reasons you can predict, not random variance:
- Recency. The API's memory ends at a training cutoff. A product that launched last quarter, a brand that renamed itself, this month's pricing, last week's round-up article - the API simply cannot know them. The web answer reads them live.
- Sources. The API answer carries no citations, because it isn't reading anything. The web answer comes back with the exact pages it pulled from - which, for anyone doing generative engine optimization, is the most useful artifact in the entire response.
- Selection. When the app searches, the brands it surfaces are shaped by what's currently rankable and citable on the open web - much closer to classic search dynamics. The API instead reflects whatever was prevalent in its training data. Those two populations are not the same.
So the same question, run through two different machines, produces a predictably different answer. The dangerous part is that the cheap answer (the API) looks authoritative - clean prose, confident tone - while quietly being a snapshot of the past.
A worked example
Take a fast-moving category - say project-management tools for remote teams. Ask "best project management tools for remote teams" through the API and you tend to get the names that were everywhere in the training data: the safe, established incumbents the model saw thousands of times. It reads well. It is also, in a churny market, a little stale.
Now ask the exact same question in the app and watch what happens. It pauses, runs a search, reads several current round-up and comparison pages, and the shelf shifts: a newer entrant that's been winning recent "best of" articles climbs in, an incumbent that's gone quiet slips, and - crucially - a list of citations appears pointing at the precise pages that shaped the answer.
Treat that as a worked example, not a study: the specific brands move by the day, the country and the user, and ChatGPT doesn't web-search every question (more on that below). The mechanic is the stable part, and it's what you can build on - when the app searches, current web evidence beats training-data memory, and you can see exactly which evidence won.
The citations are the whole game
If you take one thing from this article, take this: the source list under a web answer is the most actionable object in GEO. It is a literal map of which pages ChatGPT trusted to answer your buyer's question.
That turns a vague goal ("be more visible in AI") into a concrete to-do list. Either you are already one of the cited pages - in which case protect and strengthen it - or you aren't, in which case you now know exactly which pages you have to join or out-rank. The API gives you none of this. It can't, because it never opened a page. A tool that only reads the API can tell you whether you were mentioned; only the real web answer can tell you why, and what to do about it.
"Does it even search the web?" - sometimes
Here's an honest mechanic that trips people up. The app decides per question whether to search. Some questions it answers straight from memory - fast, no sources, indistinguishable from the API. Others it searches - slower, cited, current. Buying-intent and recency-sensitive questions ("best X," "X vs Y," "is X still the cheapest") are far more likely to trigger a search; definitional or how-to questions often don't.
This means the real signal isn't only "what did it say." It's also did it search, and what did it read. An answer with no web search and no sources is, functionally, the API answer wearing the app's clothes. Knowing which of your category's questions trigger a live search - and being strong on the pages that get cited when they do - is half the battle.
If the web answer is so much closer to reality, why does nearly every "AI visibility" tool quietly measure the API instead? Because the API is easy. It's a single HTTP request: send a question, get text back, done. You can scan a thousand questions in minutes for a few cents.
The real web answer is the opposite of easy. There is no official endpoint that returns "what the app shows." To get it, you have to drive the real app the way a person does: a real browser, getting past the bot-detection wall, then waiting twenty to forty seconds while the model actually searches and reads pages. It's slow, it fights anti-bot systems, and it breaks every time the interface changes. Multiply that by every tracked question, every brand, every day, and you see why the cheap-but-wrong number is the default the whole industry ships.
The uncomfortable trade: the API number is fast, free and stable - and a cached approximation. The real-web number is slow, fragile and expensive - and the one your buyer actually receives. We think you should know the second one, even though the first is easier to put in a chart.
What it costs to do it right
We don't want to pretend the hard path is free, so here's the real bill. A web-grounded answer takes roughly 20–40 seconds end to end, and most of that is irreducible - the model is genuinely reading multiple pages, and you cannot make reading faster without making the answer worse. It requires real browsers running under a virtual display on a server, constant work to stay ahead of bot-detection, and it has to be done per engine and per question. It is heavier than an API call by a couple of orders of magnitude.
We pay that because the cheaper number isn't the true number. A score that takes 20 seconds to compute but reflects what a customer sees beats a score that takes 200 milliseconds and reflects last year.
So which should you track? Both - for different jobs
This isn't actually an either/or. The two answers do two different jobs, and the trick is to never let them compete:
- The API is your pulse. Cheap enough to run daily, across every engine, on every question - perfect for the trend line. Is my score moving up or down? Did something break this week? The API is great for that, precisely because it's consistent.
- The real web answer is your evidence. The actual reply your buyer sees, plus the sources behind it - the ground truth you drill into when a specific number matters and you need to act on it.
One is the pulse, one is the evidence. The mistake is showing a buyer two different scores for the same brand and making them guess which is real. The discipline is: one daily pulse, and a real-web drill-down underneath it that explains and proves the pulse when you need it to.
Where Zene is today (and what we won't pretend)
Here's the honest scope. Zene captures the real ChatGPT web answer today - the actual web-searched reply and the sources it cites - sitting alongside the fast API pulse. That's live on Pro.
The other engines - Perplexity, Gemini, Grok, Claude - are rolling out, and we're not going to claim they're done before they are. Each has its own wall: some block datacenter traffic and need residential routing, some sit behind a login. We'd rather ship one engine that's genuinely real than five that quietly fall back to the cached API and call it "web." When an engine is real, we'll say so; until then it's honestly labelled as coming.
The takeaway
If you only measure the API, you're grading a photocopy. The answer that decides whether a buyer ever hears your name is the one the app gives when it searches the web - recency, citations and all. It's slower and harder to capture, which is exactly why it's worth capturing. Measure the answer people get, not the one that's easy to fetch.
Run a free audit and see what ChatGPT actually says about your brand - then look at the sources behind it.
Frequently asked questions
What's the difference between the ChatGPT API and the ChatGPT app?
The API is the model answering from its training memory - no live web by default, and no citations. The app your buyers open (chatgpt.com) classifies the question, often runs a live web search, reads pages and cites its sources. For 'what do my customers actually see when they ask AI about us', the app is the real answer; the API is a cached approximation of it.
Why does the ChatGPT API recommend different brands than the ChatGPT website?
Because they run on different supply chains. The API answers from training data frozen at a cutoff date, so it reflects what was prevalent when the model was trained. The website can search the live web, so it reflects current pages, pricing and rankings. New entrants, renamed products and recent comparison articles show up in the website's answer first - and may be invisible to the API for months.
Can I see which sources ChatGPT used to answer?
Only from the real web answer. When the app web-searches, it returns the exact pages it cited - which is the single most actionable artifact in generative engine optimization, because it tells you which pages to be on or to beat. The API returns no sources at all, because it isn't reading anything.
Why is capturing the real ChatGPT answer so much slower than the API?
Because the answer itself is slow to produce: the model genuinely runs a web search and reads several pages before it replies, which takes roughly 20–40 seconds. There's no official endpoint that returns 'what the app shows', so it has to be captured from the real app in a real browser. The bigger number isn't overhead - it's the true cost of a web-grounded answer.
 Muhammet İLBAŞ 11 min